
Technical interview questions predict job performance best when they're role-specific and scored against observable signals, not trivia recall. A practical loop usually has 4 to 6 stages, and one benchmark reports that companies interview an average of 21 candidates for one software-engineering hire, so every question must produce useful evidence.
A hiring panel can still spend an hour debating whether a candidate remembered an algorithm while nobody agrees what a good answer looks like for the actual job. That process rewards rehearsal, interviewer preference, and comfort under artificial pressure. The ten questions below connect specific prompts to full-stack, backend, DevOps, QA automation, and BI-adjacent engineering work. Each includes strong-answer signals, follow-up probes, and a clear limitation.
The format matters for distributed hiring. A shared editor, written rubric, and overlapping working hours make live scoring more consistent, including for nearshore LATAM teams. Use these questions as components in a structured loop, not as a standalone list of pass-or-fail puzzles.
1. Two Sum tests algorithmic fundamentals
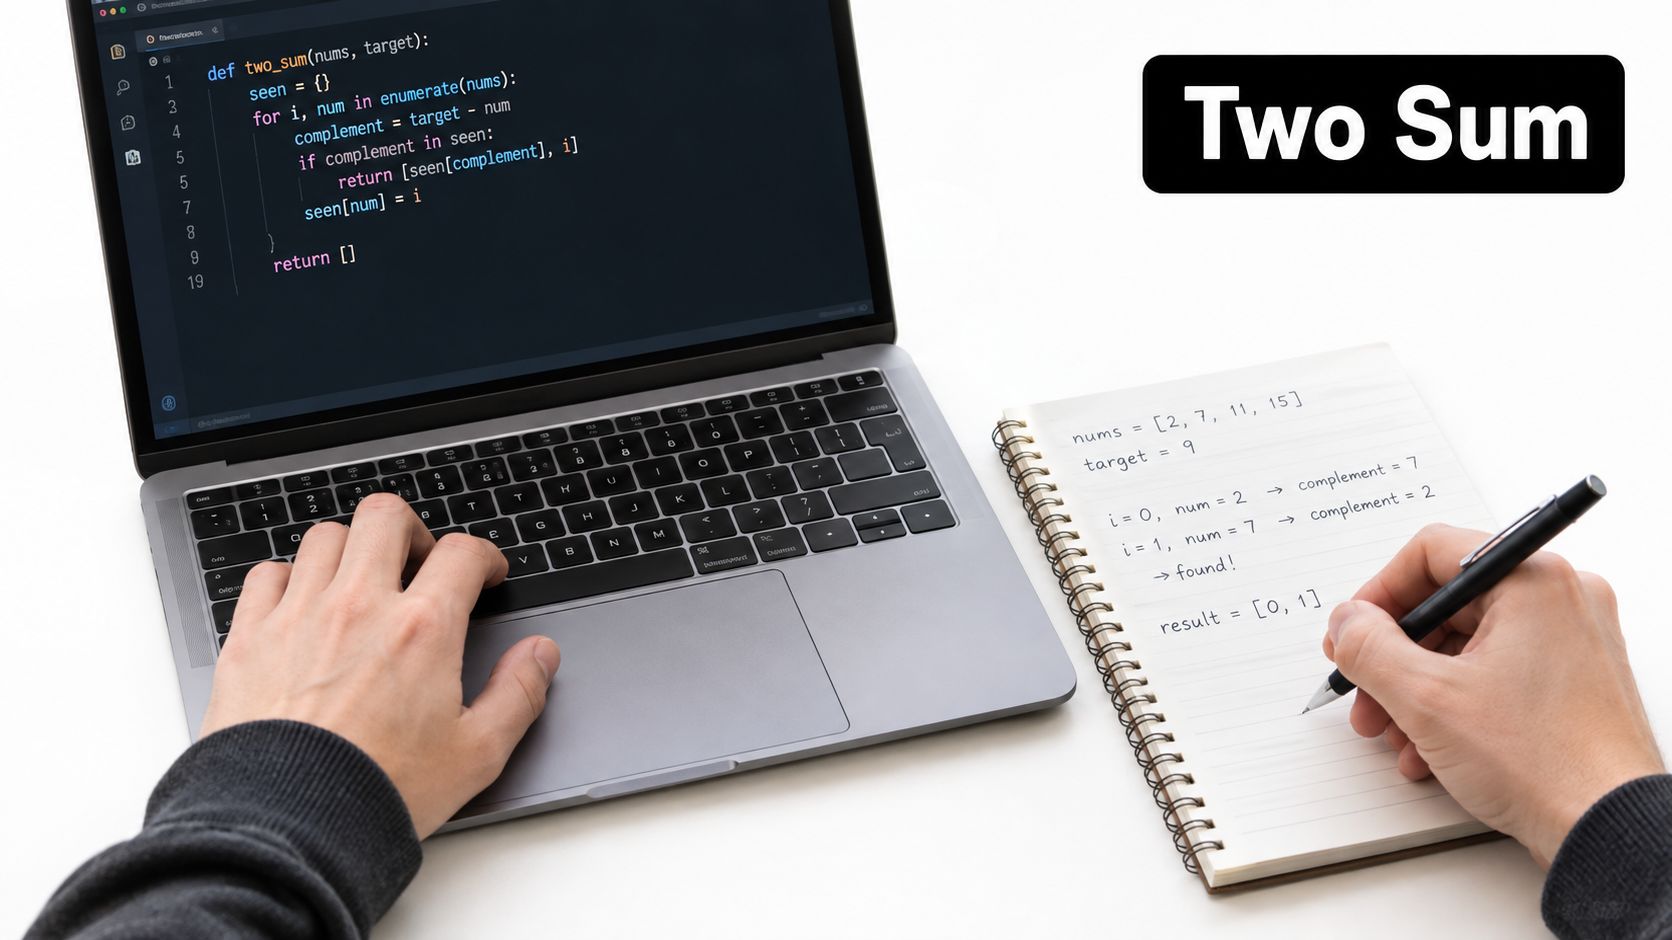
Give the candidate an array of integers and a target value. Ask them to return the indices of two values whose sum equals the target. The brute-force approach compares pairs in O(n²) time. A single-pass hash map stores previously seen values and checks each complement in O(n) time, using O(n) additional space. These complexity facts are documented in the history of modern technical interviewing by HackerRank's interview analysis.
What do you need?
Choose the hiring path that fits
After reading "10 Technical Interview Questions for Engineering Hiring", most teams compare these options before deciding how to hire.
The question fits a junior or mid-level software screen. Strong candidates clarify whether there's exactly one answer, whether negative values are allowed, and how duplicate values should behave. They explain the invariant, test a duplicate case, and distinguish time complexity from space cost before coding.
Practical rule: Use Two Sum as a screen, not a final decision.
A weak answer jumps into syntax, misses duplicate values, or produces code the candidate can't explain. Ask, “What happens when the target requires two equal values?” Then ask them to walk through the smallest valid input. Give candidates a shared editor and let them narrate. Silent coding is a weak signal, particularly when the assessment is meant to measure communication.
The limitation is familiarity. Candidates can rehearse this pattern, so pair it with a practical round that reflects the role. For distributed teams, schedule the screen inside overlapping working hours and use the same prompt, time boundary, and rubric for everyone. A collaborative format is described in guidance on pair-programming interviews.
2. Design an LRU Cache for backend depth
Ask the candidate to implement a Least Recently Used cache with constant-time average get and put operations. The standard design combines a hash map for lookup with a doubly linked list for access order. Moving a node to the front and evicting the least recently used node at the back should remain constant-time operations.
This is a better fit for mid-level and senior backend engineers than for an entry-level screen. Strong candidates state the cache invariant before writing code. They explain what the map points to, how list pointers change during insertion and eviction, and how they'll handle capacity, replacement, and a missing key.
Follow up with concurrency. Ask how they'd adapt the cache for goroutines, threads, or asynchronous workers. Look for a clear choice between a mutex, a concurrent map, ownership by one worker, or another mechanism. The answer matters less than whether the candidate identifies shared mutable state and explains the resulting trade-off.
Score invariants as carefully as code correctness. A candidate who produces compiling code but can't explain pointer updates is risky. A candidate who identifies the right design and catches a pointer edge case may deserve a stronger score than someone who memorized an implementation.
The main con is tool distortion. Restricting candidates to a whiteboard or plain-text editor can measure stress tolerance and familiarity with interview conventions rather than design ability. Let them use a simple shared environment, then inspect reasoning, tests, and corrections.
3. Second highest salary per department tests SQL judgment
Use an employees table with department and salary columns. Ask for the second-highest distinct salary in each department. A candidate might use a correlated subquery, a self-join, or a window function such as DENSE_RANK(). The important issue is not whether they choose the same syntax as the interviewer. It's whether they understand set-based reasoning and the effect of tied salaries.
State the SQL engine before the exercise. PostgreSQL, MySQL, SQL Server, and other systems differ in syntax and execution behavior. Ambiguity wastes time and rewards memorization. Seed the dataset with deliberate ties so the candidate has to decide whether “second highest” means the second row or the second distinct value.
What to probe after the query
Ask the candidate to explain the query plan and identify likely indexes. A strong answer discusses partitioning by department, ordering by salary, and the behavior of DENSE_RANK() when two employees share the highest salary. They should also explain what happens when a department has only one salary level.
A weak answer returns a plausible query but can't test it against duplicate values. Another warning sign is treating SQL as string manipulation instead of relational operations. Ask, “How would your query change if we needed the employee records, not only the salary?” That exposes whether the candidate can extend the solution without starting over.
The limitation is role mismatch. A pure SQL puzzle adds little for a frontend engineer and can understate the ability of a data professional who works mainly through transformation frameworks. Use it for BI, data, analytics engineering, and backend roles where query behavior affects production decisions.
4. Design a URL shortener for system-design reasoning
Ask the candidate to design a service that converts long URLs into short aliases and redirects visitors to the original address. Don't look for one correct architecture. Look for requirement discovery, scale reasoning, failure handling, and explicit trade-offs.
Strong candidates ask about custom aliases, expiration, analytics, abuse prevention, read-to-write ratio, and availability expectations. They may propose Base62 encoding of an auto-incrementing identifier, hashing with collision handling, or pre-generated key ranges. They should explain storage, cache behavior for hot links, redirect semantics, and how they'd handle collisions.
Ask the candidate to size the design for 10 million and 10 billion stored links. Those two scenarios force them to revisit storage, partitioning, indexing, and operational complexity. Score the requirements phase separately. A candidate who asks precise questions before drawing boxes demonstrates product judgment that a polished diagram can hide.
A weak answer lists components without stating why they fit. Another weak signal is treating analytics as an afterthought when the product requires click measurement. Ask, “What fails first, and how does the service degrade?” Then ask how they'd verify latency and redirect correctness in production.
Use a shared rubric covering requirements, data model, key generation, scalability, reliability, observability, and communication. Teams can also compare their prompt design with these API design best practices and system design templates.
5. Closures in a loop reveal JavaScript fundamentals
Show a loop that schedules callbacks with setTimeout, first using var, then using let. Ask the candidate to predict the output and explain why. The var version prints the final loop-counter value for every callback because the callbacks share the function-scoped binding. The let version prints each value in sequence because block scope creates a new binding per iteration.
This works well as a five-minute opener for a JavaScript or TypeScript role. Strong candidates mention closures, scope, and the event loop without confusing asynchronous scheduling with parallel execution. They can explain the behavior in plain language and then write a small correction, such as using let or creating a separate binding.
Follow up with a real callback-heavy function from your codebase. Ask the candidate to refactor it for readability, error handling, cancellation, or testability. That follow-up is more valuable than the output prediction because it connects language knowledge to maintainable code.
Don't make this a pass-fail gate. A candidate may remember the result but struggle to articulate the binding model, or explain the model while making a minor output mistake. Score explanation quality, correction strategy, and ability to apply the concept. Keep the prompt in TypeScript when that matches the production stack.
6. A shared counter exposes concurrency reasoning
Present two threads that increment a shared integer one million times each without synchronization. Ask for the final value and the reason. The expected result is almost never two million because each increment contains a read, a modification, and a write. Interleaving allows one thread's update to overwrite another's.
Strong candidates describe the race rather than merely naming it. They propose a mutex, an atomic integer, or message passing through a single owner goroutine or actor. They also identify the trade-off between safety, contention, throughput, and code complexity.
Follow-up questions that raise the signal
Ask the candidate to describe a concurrency bug they've debugged. Require the reproduction method, the evidence they collected, and the verification step after the fix. Then change the context: “What changes if the counter is stored in a database shared by three services?”
For payment or inventory roles, probe idempotency and transactional guarantees. A strong answer distinguishes an in-memory lock from a distributed coordination problem. A weak answer assumes a process-local mutex protects a value that multiple services can modify.
The limitation is environment dependence. The prompt may favor candidates who have worked directly with threads or low-level runtimes, while a message-oriented engineer may reason correctly using different abstractions. Score the underlying model and ask for an equivalent solution in the team's language. Don't reward vocabulary alone.
7. Diagnose a CrashLoopBackOff pod for DevOps judgment
Give the candidate a deployment whose pods repeatedly enter CrashLoopBackOff after a new image release. Ask them to diagnose it in a read-only sandbox cluster. This is a practical DevOps assessment because the candidate must form hypotheses, gather evidence, and avoid random configuration changes.
A strong sequence starts with kubectl describe and pod events, then checks logs from the previous container instance. The candidate verifies environment variables, mounted secrets, image behavior, resource limits, and liveness and readiness probes. They connect each command to a hypothesis instead of reading commands from a memorized runbook.
Ask how they'd communicate status to a product manager during the incident. Strong candidates separate investigation from stakeholder updates, state customer impact clearly, and avoid promising a root cause before evidence supports it. They should also explain rollback criteria and the next safe test.
The downside is operational access. A candidate may know the correct diagnostic sequence but lose time navigating an unfamiliar cluster or shell environment. Standardize the sandbox, permissions, image, and failure mode. Assess the quality of reasoning, evidence collection, and risk management, not command-line speed.
Teams can use DevOps interview questions as a starting point, then adapt the exercise to their own deployment model. Clear on-call documentation and overlapping working hours also help distributed teams respond consistently.
8. Diagnose a flaky end-to-end test for QA automation
Give the candidate a checkout test that passes locally but fails roughly one run in twelve in CI. Ask how they'd find and fix the cause. Strong candidates focus on mechanism, evidence, and reproducibility. They don't begin by adding retries.
Likely causes include hard-coded waits, shared data across parallel workers, unstable selectors, third-party sandbox calls, and test-order dependencies. A good candidate explains how they'd inspect CI artifacts, isolate the failure, control test data, replace timing assumptions with explicit conditions, and stub unstable external services where appropriate.
Ask how many end-to-end tests they'd keep for a checkout flow and why. The answer should distinguish a small number of high-value browser journeys from unit and integration coverage. Ask what evidence would justify deleting, rewriting, or moving a test down the pyramid.
The con is that flaky-test diagnosis can become a debate about a candidate's preferred framework. Keep the product behavior and failure evidence fixed, and let the candidate use the tools they know. Evaluate investigation discipline, test design, and communication. For international hiring, also assess whether the candidate can document the failure and write a useful incident summary in English.
A role-specific assessment can be paired with quality assurance hiring guidance, especially when the role includes automation ownership rather than only test execution.
9. Explain what happens after a browser request
Ask the candidate to describe what happens after a user presses Enter and before the page renders. Give them 8 to 10 minutes for the overview, then choose one layer for deeper probing. A complete answer covers URL parsing, DNS resolution and caching, TCP and TLS handshakes, the HTTP request and response, server processing, HTML parsing into the DOM, CSSOM construction, JavaScript execution, layout, painting, and compositing.
Strong candidates organize the lifecycle and identify where latency or failure can occur. They know that DNS may be answered from cache, that TLS affects connection setup, and that browser rendering continues through several stages after the server responds. They can connect the explanation to DevTools, tracing, resource timing, or server metrics.
Ask how they'd measure each stage in production. A frontend candidate may focus on browser performance APIs and waterfalls. A backend candidate may emphasize tracing, server timing, and dependency spans. Both can demonstrate seniority if they connect measurement to diagnosis.
The limitation is breadth. This question can punish a specialist who has deep production expertise but doesn't narrate every browser stage in textbook order. Use it to calibrate depth, not to demand a single script. Follow up on the layer most relevant to the role.
10. Fix an N+1 query in a slow orders endpoint
Provide a query log instead of application code. The endpoint lists a customer's 50 most recent orders and takes four seconds because the application loads orders, then fetches line items and product details separately inside a loop. Ask the candidate to identify the pattern, propose a fix, and explain how they'd verify the result.
Strong candidates recognize repeated queries from the log. They may propose eager loading, a join, a batched query, or a denormalized read model. The right option depends on result shape, cardinality, cache behavior, and consistency requirements. Ask how they'd avoid returning duplicate rows or loading more data than the endpoint needs.
Verification separates practical debuggers from pattern recognizers. Look for query-count assertions, an execution plan, representative data, APM traces, and endpoint latency measurements. Ask how they'd prevent regression with tests or alerts. Candidates who spot the issue directly from logs demonstrate a useful production habit.
Use the same scenario for junior and senior candidates, then compare how far each gets without hints. A junior candidate might identify the repeated queries and suggest batching. A senior candidate should discuss data shape, indexes, pagination, transaction boundaries, and observability.
The limitation is framework bias. Candidates who know a particular ORM may name eager loading faster than someone who works with SQL directly. Score the diagnosis and trade-off reasoning, not the framework vocabulary. For a broader full-stack loop, see guidance on interviewing full-stack developers and this guide to tracking metrics and alerts.
10 Technical Interview Questions: Comparison
Build a Scored Loop Around the Questions That Matter
Don't put all ten questions into one interview. Choose two or three questions per role, then pair each with a practical round that reflects the work. A backend hire might receive SQL, the N+1 diagnosis, and URL shortener design. A DevOps hire might receive the Kubernetes exercise, the concurrency follow-up, and an incident communication scenario. A QA automation hire needs flaky-test diagnosis, test design, and a small repository exercise.
Write the rubric before interviews begin. Define the competency, the evidence, and the score anchors. A practical scale might use 1 for incomplete reasoning, 3 for a workable solution with trade-offs, and 5 for production-ready reasoning. Require candidates to explain assumptions, failure modes, testing strategy, scalability, and maintainability where those dimensions apply.
Structured interviews are stronger when every candidate receives the same job-relevant questions and evidence standards. A review of structured interviews reports validity of approximately 0.42 ± 0.24 and notes lower racial-group impact than several other leading predictors in the cited research reviewed by Cambridge's Industrial and Organizational Psychology journal. Capture independent interviewer scores before discussion so the loudest voice doesn't define the result.
Interview content also needs a job-relatedness check. The U.S. Equal Employment Opportunity Commission's guidance on employment tests says interviews and performance tests must be properly validated for the specific position and purpose. Track pass rates by demographic group and review alternatives when a method creates adverse impact, as described in the EEOC's Uniform Guidelines clarification.
Finally, publish an AI policy. Standard questions can be solved with AI, and interviewers may not reliably detect quiet assistance. Assess code review, verification, debugging of generated code, security judgment, prompt formulation, and trade-offs where those skills matter. The CodePath report on what technology companies want from new hires describes this shift, so banning every tool may measure compliance with an artificial constraint rather than modern engineering competence.
Schedule scoring inside overlapping working hours and keep live rounds consistent for teams hiring across LATAM. Where sourcing is the bottleneck, GENTY's IT recruitment service can supply curated shortlists while your engineering leaders retain ownership of the rubric. Use the same standard for technical ability, communication, debugging, and operational judgment.
This guide to culture-fit interviews can help with the separate behavioral layer, but don't let culture fit replace evidence from the technical loop. The hiring decision should show which role capabilities the candidate demonstrated, where the evidence was incomplete, and what risk remains.
GENTY recruitment helps companies hire curated tech talent across Latin America, including full-stack developers, DevOps engineers, QA automation specialists, and BI developers. If your team needs role-specific shortlists to run this kind of scored interview loop, visit GENTY recruitment and discuss your hiring requirements.